

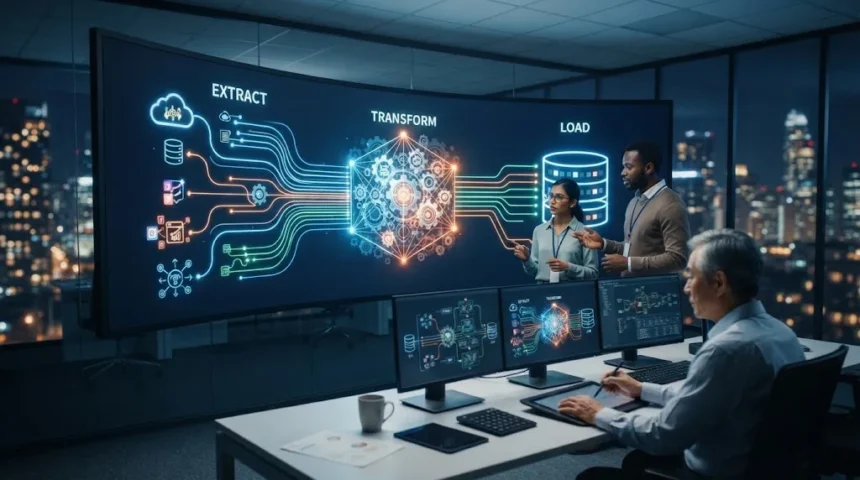
Businesses collect data from many different places, including websites, applications, customer relationship management platforms, payment systems, spreadsheets, and cloud databases. However, this information is rarely ready for analysis in its original form. ETL helps organizations collect data from different sources, clean and organize it, and move it into a centralized system where it can be used more effectively.
ETL stands for Extract, Transform, and Load. These three stages form a common data processing workflow used in analytics, business intelligence, reporting, and data warehousing. By understanding how ETL works, organizations can improve data quality, reduce manual preparation, and make information easier for analysts, managers, and decision-makers to access and understand.
What Is ETL?
ETL is a data integration process that collects information from one or more sources, changes it into a useful format, and loads it into a destination system. The destination may be a data warehouse, database, analytics platform, or another centralized storage environment. ETL helps bring disconnected information together so teams can analyze it consistently.
The three stages are extraction, transformation, and loading. Extraction retrieves the original data, transformation cleans and restructures it, and loading places the processed information into the target system. Each stage has a different purpose, but they work together as one pipeline that turns raw source data into analysis-ready information.
ETL is especially useful when organizations depend on several applications that store data differently. A sales platform may use one customer identifier while a billing system uses another format. ETL processes can standardize those differences so records can be combined and used accurately in reports and dashboards.
Why ETL Is Important
Organizations often have valuable information scattered across multiple systems. Without ETL, analysts may need to manually download files, clean spreadsheets, correct formats, and combine datasets every time they create a report. This repeated work is inefficient and increases the risk of inconsistencies or human error.
ETL creates a repeatable process for preparing data. Once a pipeline is configured, information can be extracted, transformed, and loaded automatically according to a schedule or trigger. This allows analysts to spend more time interpreting business performance instead of repeatedly performing basic preparation tasks.
Reliable ETL also improves trust in reporting. When the same transformation rules are applied consistently, departments are less likely to produce conflicting results from identical source systems. Standardized pipelines can therefore improve dashboards, financial reports, customer analytics, operational monitoring, and other data-driven activities across the organization.
Step 1: Extracting the Data
Extraction is the first stage of the ETL process. During this step, data is retrieved from one or more source systems. Common sources include relational databases, cloud applications, APIs, spreadsheets, CRM systems, enterprise software, website platforms, sensors, and flat files such as CSV or JSON documents.
The extraction method depends on how the source system stores and provides information. Some databases allow direct queries, while cloud applications may require API connections. In other cases, businesses may receive scheduled files from external partners or use connectors designed specifically for certain platforms.
Extraction should be designed carefully so it does not place unnecessary stress on operational systems. Pulling large amounts of information during peak business hours can sometimes affect performance. Many ETL pipelines therefore extract only new or changed records rather than copying an entire database every time the process runs.
Step 2: Transforming the Data
Transformation is often the most complex part of ETL because raw information usually needs cleaning before it becomes useful. During this stage, records may be standardized, validated, filtered, combined, or enriched. Incorrect formats, duplicates, missing values, and inconsistent naming conventions may also be addressed.
For example, one system may store dates as MM/DD/YYYY while another uses YYYY-MM-DD. An ETL transformation can convert both formats into one consistent standard. Similarly, customer names, product categories, currency values, phone numbers, and geographic fields can be standardized before loading.
Transformations can also create new calculated fields. A business may combine quantity and unit price to calculate order revenue or group individual products into broader categories for reporting. These rules turn raw operational data into information that is easier to analyze across dashboards and business intelligence systems.
Step 3: Loading the Data
Loading is the final stage in the traditional ETL process. After information has been extracted and transformed, it is moved into the target system. This destination is often a data warehouse, although ETL pipelines can also load information into databases, reporting systems, data marts, or other analytical platforms.
Data may be loaded in several ways depending on business requirements. A full load replaces or imports an entire dataset, while an incremental load adds only new or updated records. Incremental loading is often more efficient because it reduces processing time and avoids repeatedly moving information that has not changed.
The load process also needs validation. Teams may check row counts, rejected records, timestamps, or totals to make sure information arrived correctly. Monitoring these checks helps identify pipeline failures before inaccurate or incomplete data appears in dashboards, financial reports, or other important analytical outputs.
ETL Example in a Real Business
Imagine an online retailer using one platform for orders, another for customer support, and a separate marketing system. Each platform contains useful information, but the records are stored differently. The company wants one dashboard showing revenue, customer activity, support interactions, and marketing performance.
An ETL pipeline first extracts information from each system. It then standardizes customer IDs, fixes date formats, removes unnecessary fields, and combines related records. The transformed information can then be loaded into a central data warehouse where reporting tools can access it.
Managers can now review company performance without manually combining multiple spreadsheets. Marketing teams can compare campaigns with actual sales, while support teams can connect customer issues with purchasing behavior. ETL turns several disconnected systems into a more consistent source of business intelligence.
ETL and Data Integration
ETL is one approach within the broader field of data integration. Data integration focuses on combining information from multiple systems so it can be accessed and used together. ETL specifically follows an extract-transform-load sequence where preparation takes place before information reaches the final destination.
Organizations exploring different data integration methods may also encounter APIs, data virtualization, replication, streaming, and other approaches. ETL remains widely useful when businesses need structured, cleaned information for reporting and analytics rather than simply connecting applications in real time.
The right integration approach depends on how quickly data is needed and what will happen to it afterward. ETL is well suited to recurring analytical pipelines, while real-time integration may be more appropriate for operational applications. Many organizations use several methods rather than relying on one technique everywhere.
ETL vs ELT
ETL and ELT use the same three basic activities but perform them in a different order. ETL transforms information before it reaches the destination, while ELT extracts the data, loads it first, and performs transformations inside the target environment. Modern cloud platforms have made ELT increasingly common.
ELT can be useful when the destination provides powerful computing resources and organizations want to retain large amounts of raw information. Data engineers can load records quickly and create different transformations later. This approach offers flexibility when analytical requirements change frequently or data volumes become very large.
Traditional ETL can still be valuable when organizations want carefully prepared information before it enters the destination. It can reduce unnecessary storage and help enforce quality rules early in the pipeline. The choice between ETL and ELT depends on architecture, data volume, performance needs, governance, and available technology.
ETL and Data Warehouses
ETL has historically played a major role in data warehouse architecture. Operational systems are designed to run everyday business activities, while data warehouses are optimized for reporting and analytics. ETL moves information from operational sources into a structured environment where business users can analyze it efficiently.
Before entering the warehouse, records may need extensive transformation. Customer identifiers might be matched, product categories standardized, and transaction information converted into consistent formats. These steps help create reliable datasets that can support dashboards and recurring reports across different departments.
A well-designed ETL process also preserves historical information. Operational systems may change records over time, while warehouses often need to maintain older values for comparison. ETL pipelines can capture changes so analysts can study trends across months or years instead of seeing only the latest state.
Common ETL Transformation Techniques
Filtering is one of the simplest ETL transformation techniques. Pipelines can exclude unnecessary records or columns before loading data into the destination. Removing irrelevant information reduces storage requirements and makes downstream datasets easier for analysts to understand and use.
Data standardization is equally important. Fields such as country names, phone numbers, currencies, product categories, and timestamps may appear in several formats across different systems. ETL rules can convert those values into one agreed structure, reducing confusion and improving consistency across reporting.
Other common transformations include deduplication, aggregation, joining, validation, and enrichment. An ETL pipeline may combine customer records, summarize daily transactions, reject invalid values, or add geographic information. The exact transformations depend on the questions the organization needs its data to answer.
Benefits of ETL
One major ETL benefit is improved data quality. Automated transformation rules can identify duplicate records, inconsistent fields, invalid values, and missing information before data reaches analytical users. Cleaner inputs create more reliable dashboards and reduce time spent correcting problems after reports have already been built.
ETL also improves efficiency by automating repetitive preparation work. Instead of manually combining files every week, organizations can schedule pipelines to update reporting systems automatically. This can reduce workload for analysts and make updated information available more consistently across departments.
Another advantage is improved accessibility. Data from many systems can be combined into one structured destination with consistent definitions. Finance, sales, marketing, and operations teams can then work from shared datasets rather than maintaining separate spreadsheets that may contain different versions of the same business information.
Common ETL Challenges
Poor source data is one of the biggest ETL challenges. If information is incomplete, inconsistent, or incorrectly entered, transformation rules may become complicated. Teams need to decide whether bad records should be corrected automatically, rejected, flagged for review, or loaded with warnings.
Changing source systems can also cause pipeline failures. An application provider may rename fields, modify an API, or change the structure of an exported file. ETL pipelines must be monitored so these changes can be detected before they interrupt reporting or create incomplete datasets.
Performance becomes another concern as data volumes grow. Large pipelines can consume significant computing resources, especially when transformations involve complex joins or repeated processing. Efficient incremental extraction, partitioning, scheduling, and optimization help keep ETL workflows manageable as an organization scales.
ETL Tools and Technologies
ETL tools help automate extraction, transformation, workflow management, scheduling, and loading. Some platforms provide visual drag-and-drop interfaces, while others rely more heavily on SQL, Python, or configuration files. The best option depends on technical skills, data sources, infrastructure, and the complexity of the pipelines being created.
Cloud-based ETL services have become increasingly popular because organizations can scale resources as workloads grow. These platforms often include connectors for common databases and software applications. They can also integrate with cloud storage, warehouses, monitoring services, and other components in a modern data environment.
Open-source and custom ETL approaches are also common. Data engineering teams may build pipelines using programming languages, workflow schedulers, and database tools when they need more control. There is no single best ETL technology because each organization has different data volumes, budgets, security requirements, and architecture.
ETL Best Practices
Start by clearly defining what the pipeline needs to accomplish. Identify the source systems, destination, update frequency, transformations, and business users before building the workflow. Clear requirements reduce unnecessary complexity and make it easier to validate whether the final dataset meets reporting needs.
Build data quality checks into each important stage. Monitor record counts, missing values, duplicate rates, unexpected schema changes, and failed transformations. Automated alerts can help teams respond quickly when a pipeline produces unusual results rather than discovering problems later through an inaccurate dashboard.
Documentation is equally important. Record where data comes from, how fields are transformed, who owns the pipeline, and what happens when an error occurs. Good documentation makes troubleshooting easier and helps new analysts or engineers understand the logic without reverse-engineering every transformation.
How ETL Supports Business Analytics
Analytics depends on having information that is accessible, consistent, and understandable. ETL prepares data before analysts begin building reports, calculating metrics, or exploring patterns. This preparation can reduce the amount of manual cleaning required every time someone wants to answer a business question.
For example, sales and marketing information may come from separate platforms. ETL can combine campaign data with customer and transaction records so teams can analyze revenue by marketing source. Without this integration, employees might spend hours manually matching spreadsheets before meaningful analysis can begin.
ETL also supports repeatable reporting. Once transformations are standardized, recurring dashboards can update automatically using the same business logic. Decision-makers receive more consistent results because calculations are no longer rebuilt differently by individual analysts every time a report is produced.
Conclusion
ETL stands for Extract, Transform, and Load, and it provides a structured way to move data from source systems into an analytical destination. Extraction collects information, transformation cleans and organizes it, and loading places the prepared data into a warehouse, database, or reporting environment.
The main value of ETL comes from consistency and automation. It can improve data quality, reduce manual preparation, connect information from different systems, and create dependable datasets for analytics. These benefits make ETL an important part of many business intelligence and data engineering workflows.
Modern organizations may use traditional ETL, ELT, real-time integration, or a combination of several approaches. The right choice depends on data volume, infrastructure, speed, governance, and business requirements. Regardless of architecture, reliable data pipelines remain essential for turning scattered information into meaningful insights.
FAQs
What does ETL stand for?
ETL stands for Extract, Transform, and Load. It describes a process where data is collected from source systems, cleaned or reorganized, and then moved into a destination for analysis or reporting.
What is an example of ETL?
An online retailer might extract orders from an e-commerce platform, standardize customer and product information, and load the cleaned records into a data warehouse for sales dashboards and analysis.
What is the difference between ETL and ELT?
ETL transforms data before loading it into the destination. ELT loads raw data first and performs transformations afterward, often using the computing capabilities of a modern cloud warehouse or lakehouse.
Why is ETL important for data analysis?
ETL prepares information by cleaning, standardizing, combining, and validating records before analysis. This reduces manual preparation and helps analysts work with more consistent and trustworthy datasets.
Is ETL still used today?
Yes. ETL remains widely used for data warehousing, reporting, migration, and integration. Many organizations also use ELT and real-time pipelines alongside traditional ETL depending on their architecture and analytical requirements.
