

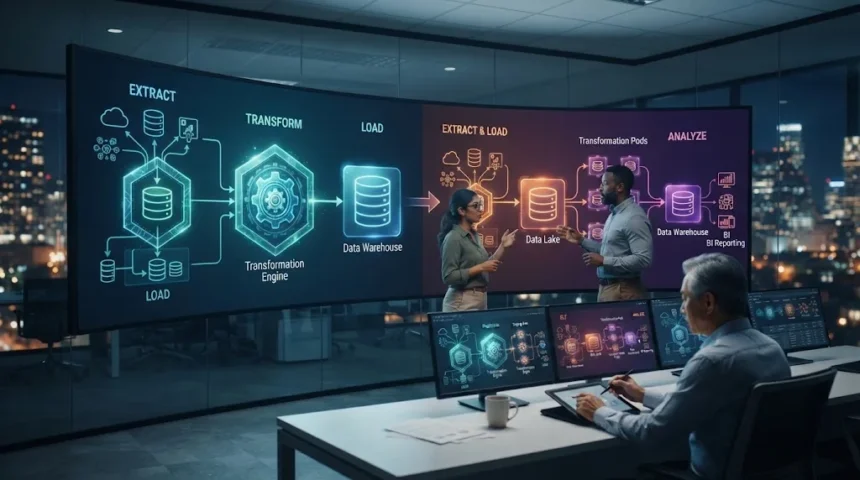
ETL and ELT are two common methods for moving data from source systems into a destination where it can be stored, analyzed, and used for reporting. Both approaches begin by extracting information from databases, applications, spreadsheets, APIs, or other sources. The main difference is when the data transformation step happens during the overall pipeline.
ETL stands for extract, transform, and load. Data is collected from source systems, cleaned and reshaped in a separate processing environment, and then loaded into a destination such as a data warehouse. This approach has been used for decades because it allows organizations to control data quality before information reaches the analytical system.
ELT stands for extract, load, and transform. Raw data is extracted and loaded into the destination first, then transformed using the computing power available inside that platform. ELT has become increasingly common with modern cloud data warehouses because these systems can store large datasets and perform complex transformations efficiently.
What Is ETL?
ETL begins by extracting data from one or more sources. These sources may include transactional databases, customer relationship management platforms, accounting systems, marketing applications, or flat files. The extracted information is moved into a staging or processing environment where teams can prepare it before it enters the final data warehouse or analytical system.
During transformation, data may be cleaned, standardized, filtered, joined, or calculated according to business rules. Duplicate records can be removed, date formats aligned, customer identifiers matched, and missing values handled. If you want a deeper explanation of the process, this guide to ETL covers how extract, transform, and load workflows work in practice.
After transformation, the prepared data is loaded into the destination. Because the information has already been cleaned and structured, analysts can often begin using it immediately. This makes ETL particularly useful when organizations require controlled schemas, strong validation, and highly consistent datasets for business intelligence, financial reporting, or regulated environments.
What Is ELT?
ELT changes the order by loading raw information into the destination before transforming it. Data is extracted from source systems and moved directly into a cloud warehouse, data lakehouse, or other scalable storage environment. Transformations are then performed inside that destination using its own computing resources rather than a separate transformation server.
This approach allows organizations to preserve raw data while creating multiple transformed versions for different analytical needs. A data science team may use one transformation, while finance or marketing teams may require different structures. Because the raw information remains available, teams can rebuild models later without always returning to the original source systems.
ELT works especially well with cloud platforms that separate storage and compute or provide scalable processing resources. The destination can handle large volumes of data and run transformations when needed. This flexibility makes ELT attractive for modern analytics environments where requirements change frequently and teams want fast access to newly collected information.
ETL vs ELT: The Main Difference
The primary difference between ETL and ELT is the order of transformation and loading. ETL transforms information before it reaches the final destination, while ELT loads raw data first and transforms it afterward. This simple change affects performance, architecture, governance, flexibility, and how quickly new information becomes available to analysts.
ETL gives organizations more control over what enters the warehouse because data is cleaned before loading. This can reduce unnecessary storage and help maintain a highly structured analytical environment. However, transformation can become a bottleneck when very large datasets must be processed before users can access them.
ELT prioritizes fast ingestion and flexible transformation. Raw information reaches the destination quickly, where different teams can transform it according to their needs. The trade-off is that organizations must manage raw and transformed datasets carefully so users know which tables are trusted and which still require cleaning or validation.
How the ETL Process Works
The extraction stage collects information from source systems while minimizing disruption to those applications. Some pipelines perform full extracts, while others only collect records that have changed since the previous run. Choosing the right extraction method can reduce processing time and prevent unnecessary movement of large datasets.
Transformation is usually the most complex stage. Data engineers may apply business rules, convert formats, combine records, create calculated fields, remove invalid entries, and standardize values. These steps ensure that the destination receives information that follows agreed definitions and is ready for consistent reporting or analytical use.
The load stage moves the prepared dataset into the target platform. Loading can occur in scheduled batches or through incremental updates depending on business needs. Once complete, dashboards, reports, and business intelligence tools can query the warehouse without repeatedly performing the same cleaning logic each time users need information.
How the ELT Process Works
ELT starts with extraction in much the same way as ETL. Data is collected from business applications, databases, APIs, event streams, and files. Instead of waiting for extensive preparation, the pipeline moves that information into the target platform relatively quickly so the source data becomes available for future transformation.
The loading stage happens before most business logic is applied. Raw data may be stored in dedicated schemas, tables, or storage layers that separate it from trusted analytical datasets. This makes it possible to preserve an original copy while teams create transformed models without altering the source version.
Transformation then occurs inside the destination. SQL-based modeling tools, warehouse functions, or data transformation frameworks can convert raw information into clean analytical tables. Teams can rerun those transformations whenever definitions change, making ELT particularly flexible when business requirements evolve or several departments need different versions of the same underlying data.
ETL vs ELT for Data Warehouses
Traditional data warehouses were commonly designed around ETL because storage and computing resources were relatively expensive. Organizations wanted to clean and reduce information before loading it into the warehouse. This approach also helped enforce structured schemas and kept analytical environments focused on data that had already been approved for reporting.
Modern cloud warehouses have made ELT more practical by providing affordable storage and scalable processing power. Companies can load larger amounts of raw information and decide later which transformations are needed. This supports faster ingestion while allowing analysts and engineers to build new models without constantly redesigning upstream pipelines.
Both methods can still work with modern warehouses. A company may use ETL for sensitive financial information and ELT for large behavioral datasets that need flexible exploration. The best architecture often combines techniques based on data type, governance requirements, processing cost, and how quickly teams need access to new information.
Performance and Scalability Differences
ETL performance depends heavily on the system used for transformation. Large datasets can take significant time to process before loading, especially when several joins, validation rules, or calculations are required. If the transformation infrastructure cannot scale easily, pipeline delays may grow as data volume increases across the organization.
ELT uses the destination platform’s processing power, which can make scaling easier in cloud environments. Many modern warehouses allow teams to add more compute resources when transformations become demanding. This can shorten processing time, although additional compute usage may also increase cost if workloads are poorly optimized.
Scalability should therefore be evaluated alongside efficiency. ELT is not automatically faster in every situation, and ETL is not automatically outdated. Pipeline design, data volume, transformation complexity, platform architecture, and query patterns all influence performance, making testing with realistic workloads important before selecting one method for every dataset.
Data Quality and Governance
ETL can make governance easier because information is validated before entering the destination. Business rules can prevent incomplete or invalid records from reaching trusted reporting tables. This is useful when analysts need highly controlled datasets and when regulatory or financial requirements demand strict validation before information becomes broadly available.
ELT introduces more raw data into the destination, which creates additional governance responsibilities. Teams need naming conventions, access controls, documentation, and clear separation between raw and trusted layers. Without those controls, users may accidentally query incomplete datasets and produce reports that conflict with approved business metrics.
Strong governance can make either method reliable. Organizations should document where data comes from, who owns it, how transformations are applied, and which datasets are approved for use. Data quality monitoring should also continue after pipelines are deployed because source systems, schemas, and business definitions can change over time.
ETL vs ELT for Security and Compliance
ETL can reduce exposure to sensitive information by masking, filtering, or removing protected fields before loading data into an analytical system. Personally identifiable information or confidential values can be transformed before they reach broader reporting environments. This may simplify access management when only limited portions of the original dataset are required.
With ELT, raw information is loaded before transformation, which means the destination may temporarily or permanently contain sensitive source data. Strong permissions, encryption, masking, and role-based access become especially important. Teams should clearly define who can access raw layers and whether certain fields should be excluded during ingestion.
Compliance requirements vary by industry and region, so security architecture should be designed around actual obligations rather than assumptions. Either ETL or ELT can support secure data processing when implemented carefully. The key is understanding where sensitive information exists at each stage and applying protection consistently throughout the pipeline.
Cost Differences Between ETL and ELT
ETL may require dedicated transformation infrastructure or specialized integration platforms. Costs can include software licensing, servers, maintenance, and engineering time needed to manage pipelines. Processing data before loading can reduce warehouse storage requirements, but the external transformation environment may become expensive as data volume and complexity increase.
ELT can simplify infrastructure by using the cloud warehouse for transformation, but that does not make it free. Storing raw information increases storage usage, and large transformations can consume significant compute resources. Inefficient queries or repeated full-table processing can create unexpected bills when teams do not monitor workload behavior carefully.
Organizations should compare total cost rather than focusing only on individual software prices. Consider storage, computing, licensing, engineering effort, monitoring, maintenance, and expected growth. The cheaper approach for a small reporting environment may not remain cheaper once the business processes billions of records or supports dozens of analytical teams.
When to Choose ETL
ETL can be a strong choice when data must be cleaned or protected before entering the destination. Organizations with strict compliance requirements, highly structured reporting needs, or limited warehouse resources may prefer this approach. It provides a controlled pathway where only approved and transformed information reaches the main analytical environment.
It can also work well when schemas and business rules are stable. If a company already knows exactly how financial, sales, or operational data should be structured, transforming it before loading may create an efficient and predictable workflow. Analysts receive standardized information without needing to understand complex raw source formats.
However, teams should consider whether transformation requirements are likely to change frequently. Rebuilding upstream ETL pipelines every time a business definition changes can become slow and difficult. If many teams need different versions of the same data, a more flexible ELT-style architecture may reduce the amount of repeated pipeline development.
When to Choose ELT
ELT is often suitable when organizations use scalable cloud warehouses and want fast access to raw information. It allows teams to ingest data quickly and postpone transformation until specific analytical requirements are understood. This can be valuable for growing businesses where new reporting, machine learning, and data science use cases appear frequently.
It also supports experimentation. Analysts can build new transformations without requesting a completely new ingestion pipeline every time they want to test a business question. Because raw information remains available, teams can create multiple models from the same source and revise those models when requirements change.
ELT still requires disciplined governance. Raw data should not be treated as automatically trustworthy simply because it exists inside a powerful warehouse. Clear modeling layers, documentation, access controls, and quality checks are essential if organizations want flexibility without creating a confusing environment filled with duplicate or inconsistent datasets.
Conclusion
ETL and ELT both move data from source systems into platforms where it can support analytics, reporting, and decision-making. The key difference is the order of operations: ETL transforms data before loading it, while ELT loads data first and transforms it inside the destination. That change influences architecture, speed, flexibility, governance, and cost.
ETL remains useful when organizations need strong control before data reaches the warehouse, especially for structured reporting or sensitive information. ELT works well with scalable cloud platforms where raw information can be stored cheaply and transformed repeatedly. Neither method is universally better, and many businesses use both depending on the dataset.
The right choice should reflect your data volume, cloud architecture, compliance requirements, engineering resources, and analytical goals. Test realistic workloads and consider long-term maintenance before committing to one approach. A well-designed pipeline matters more than whether it carries an ETL or ELT label.
FAQs
What is the main difference between ETL and ELT?
ETL transforms data before loading it into the destination, while ELT loads raw data first and transforms it afterward. This difference affects flexibility, scalability, governance, and how quickly information becomes available.
Is ELT better than ETL?
Not always. ELT can be more flexible for modern cloud environments, while ETL may be preferable when data must be cleaned, filtered, or protected before entering the target system.
Why is ELT popular with cloud data warehouses?
Cloud warehouses provide scalable storage and computing power, allowing organizations to load raw information quickly and perform transformations later. This makes it easier to support changing analytical requirements and large datasets.
Can a company use ETL and ELT together?
Yes. Many organizations use ETL for controlled or sensitive datasets and ELT for flexible cloud analytics. A hybrid approach can match different processing methods to different business and governance requirements.
Which is easier to maintain, ETL or ELT?
Maintenance depends on architecture and team skills. ELT can simplify ingestion and transformation changes, while ETL can produce cleaner destination environments. Good documentation, monitoring, and governance matter more than the method alone.
